Ian Buck, Nvidia vice president
Recent presentation on 'AI factory efficiency'
AI infrastructure benchmark shifting to 'tokens per watt'
Agentic AI expansion drives up enterprise costs
Samsung Electronics, SK hynix improve HBM bandwidth
PIM and CXL in development as future memory solutions
The benchmark for AI semiconductor performance is shifting from raw computing power to token output — how many tokens a system can generate quickly under fixed power and cost constraints increasingly determines the profitability of an AI data center.
The global semiconductor industry is racing to find answers for the age of tokenomics. Nvidia, which leads AI computing technology, is maximizing token throughput at AI factories by optimizing power efficiency. The world's two largest memory chipmakers, Samsung Electronics and SK hynix, are advancing HBM technology while also adding computing functions to memory chips to keep pace with the market shift.
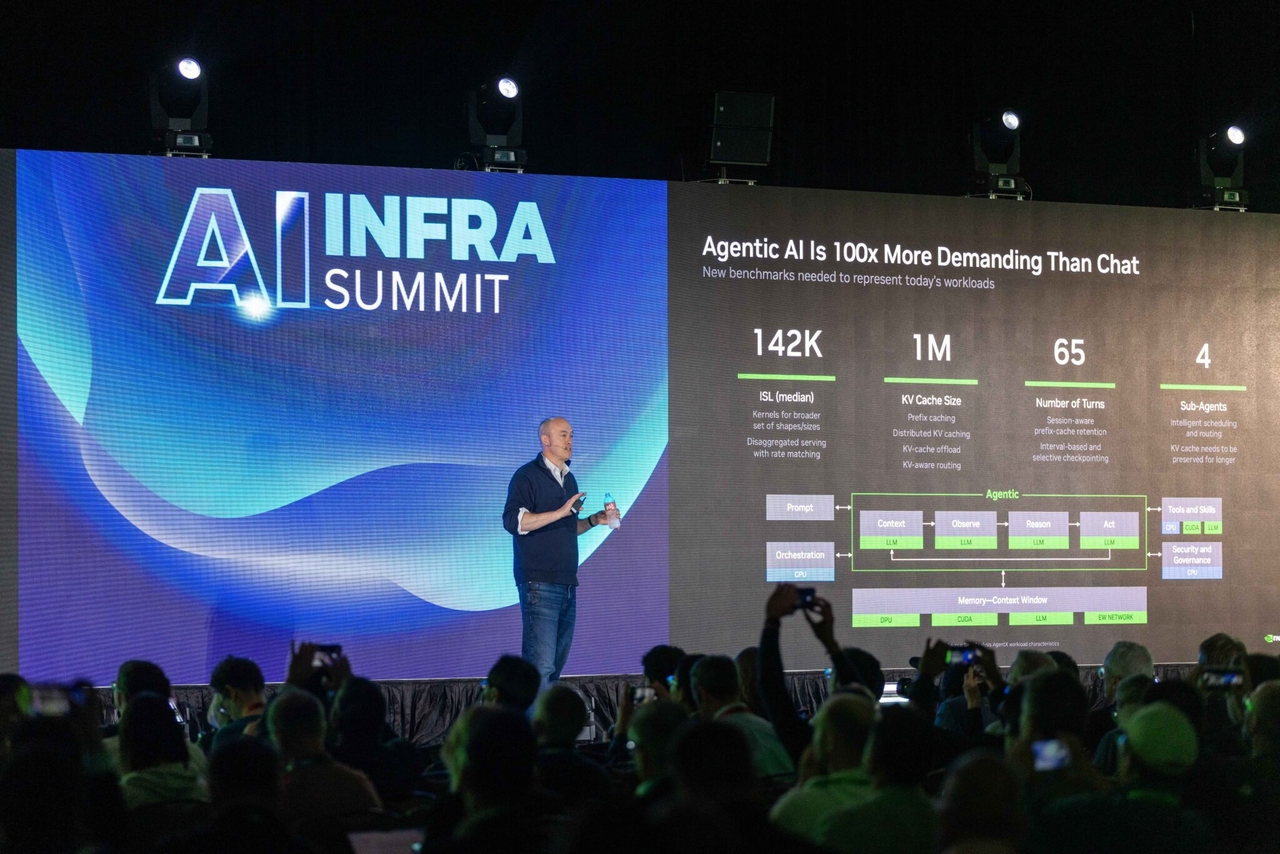
At the AI Infrastructure Summit held earlier this month in Santa Clara, California, Ian Buck, Nvidia's vice president of hyperscale and high-performance computing, delivered a presentation on AI factory efficiency, according to industry sources.
Buck described a trend in which the benchmark for AI infrastructure is moving away from peak performance toward "agentic tokens per megawatt." Nvidia, he said, is leading optimization efforts spanning everything from semiconductors to power grids.
Nvidia said its Blackwell server-based DSX MaxLPS has boosted token output per megawatt by up to 1.4 times. The system continuously monitors power consumption across GPUs and racks and dynamically reallocates available power where it is needed. AI cloud provider Lambda jointly announced the proof-of-concept results with Nvidia at the summit.
"This proof of concept confirmed that we can push beyond the limits of a fixed power budget," said Dave Ward, president of Lambda's cloud services division. "Nvidia DSX MaxLPS dramatically increases computing density within the same footprint, opening a path to converting previously untapped power capacity into genuinely usable resources."
A token is the basic unit into which AI breaks down data such as text and images for processing. The more tokens a system handles per second, the faster a large language model can deliver responses. Token usage is surging particularly as agentic AI — systems capable of autonomous reasoning — becomes more widespread.
Companies actively adopting AI are accepting rising token costs as an unavoidable reality. Analysts say token expenses are on track to become a fixed cost on corporate balance sheets. Improving token productivity will only grow in importance as businesses using AI models seek to protect their margins.
Chipmakers such as Samsung Electronics and SK hynix are looking to boost token productivity through advances in memory technology. For now, they are focused on increasing HBM bandwidth to relieve AI bottlenecks.
The seventh-generation HBM4E — for which both companies provided samples to major customers in the first half of this year — delivers higher bandwidth and better energy efficiency than its predecessor. Samsung Electronics' HBM4E offers 3.6 terabytes per second of bandwidth, maximizing LLM computation speeds. SK hynix has achieved a per-pin data transfer rate of up to 16 Gbps.
Processing-In-Memory, or PIM, cited as a future memory technology, is also emerging as a leading token-optimization solution. Samsung Electronics unveiled its LPDDR5X-PIM last month, adding computing functions to low-power DRAM. SK hynix showcased its "AiM" chip — memory with built-in computing capability — and the "AiMX" accelerator card, which houses multiple AiM chips, at the AI Infrastructure Summit 2026.
When low-power DRAM handled only data storage, information had to be sent to processors such as CPUs and GPUs for computation. But when memory handles simple calculations directly, bandwidth can be dramatically improved.
Where to store the KV cache — the key-value cache that grows as LLM conversations lengthen — also affects token output. CXL, or Compute Express Link, is seen as the answer, as it can dramatically expand memory storage capacity. CXL is a next-generation interconnect technology that enables CPUs, GPUs and memory to communicate seamlessly. Both companies are preparing for market adoption through CXL-based memory modules.
jeongwan@heraldcorp.com