- Filters redundant training data and distributes it efficiently across GPUs
- Reduces training time for medical and coding AI models by up to 69.6%
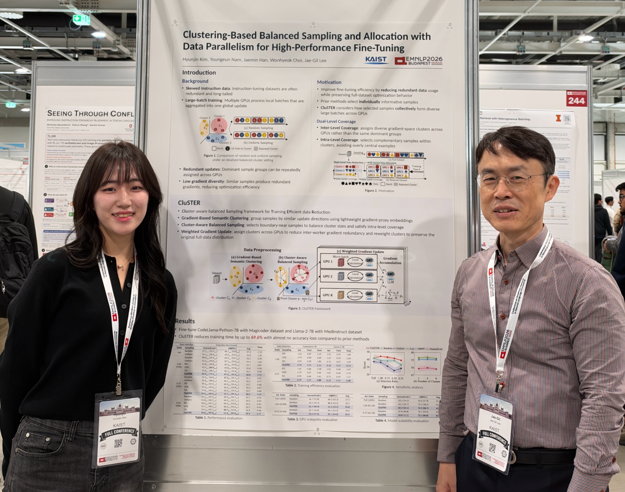
South Korean researchers have developed a technology that can cut the time required to train AI models by nearly 70 percent, potentially slashing the time and cost of building AI systems tailored to specialized fields such as medicine and coding.
KAIST announced Monday that a research team led by Professor Lee Jae-gil of the School of Computing had developed CluSTER, a fine-tuning technology for large language models that efficiently selects training data and distributes it across multiple GPUs.
Fine-tuning a large language model — such as ChatGPT — for specialized domains like medicine or coding requires additional training on domain-specific data. The process, however, demands enormous GPU computing resources and time because vast amounts of data must be processed repeatedly.
In conventional approaches, training data is distributed randomly across GPUs, creating inefficiencies when data with overlapping learning effects is processed multiple times. Even with a large number of GPUs, a significant portion of the computation does not translate into actual improvements in AI performance.
To address this, the research team shifted focus from the volume of training data to its "learning effect."
CluSTER analyzes the influence each data sample has on AI training and groups together samples that produce similar learning outcomes. Rather than simply assessing whether sentences or topics are alike, the technology examines how similar the actual knowledge and capabilities the AI acquires from each sample are.
For example, a problem asking a student to add two apples and three apples, and one asking to add two pencils and three pencils, are expressed differently but train the same addition skill. CluSTER identifies such overlapping learning effects to minimize unnecessary repetition in training.
The system then selects only the necessary samples from each data cluster and distributes them so that multiple GPUs each handle distinct learning information. The key is reducing the total training load while preserving the full range of knowledge the AI needs to acquire.
The team validated the approach in experiments using three coding and medical training datasets on large language models with approximately 7 billion and 13 billion parameters.
Using only about 31 percent of the full training dataset, the team cut training time by up to 69.6 percent while maintaining nearly the same level of AI performance — the equivalent of completing in roughly three hours what would otherwise take 10 hours.
Performance was primarily verified in a four-GPU environment, and the technology also outperformed conventional methods in an eight-GPU setup.
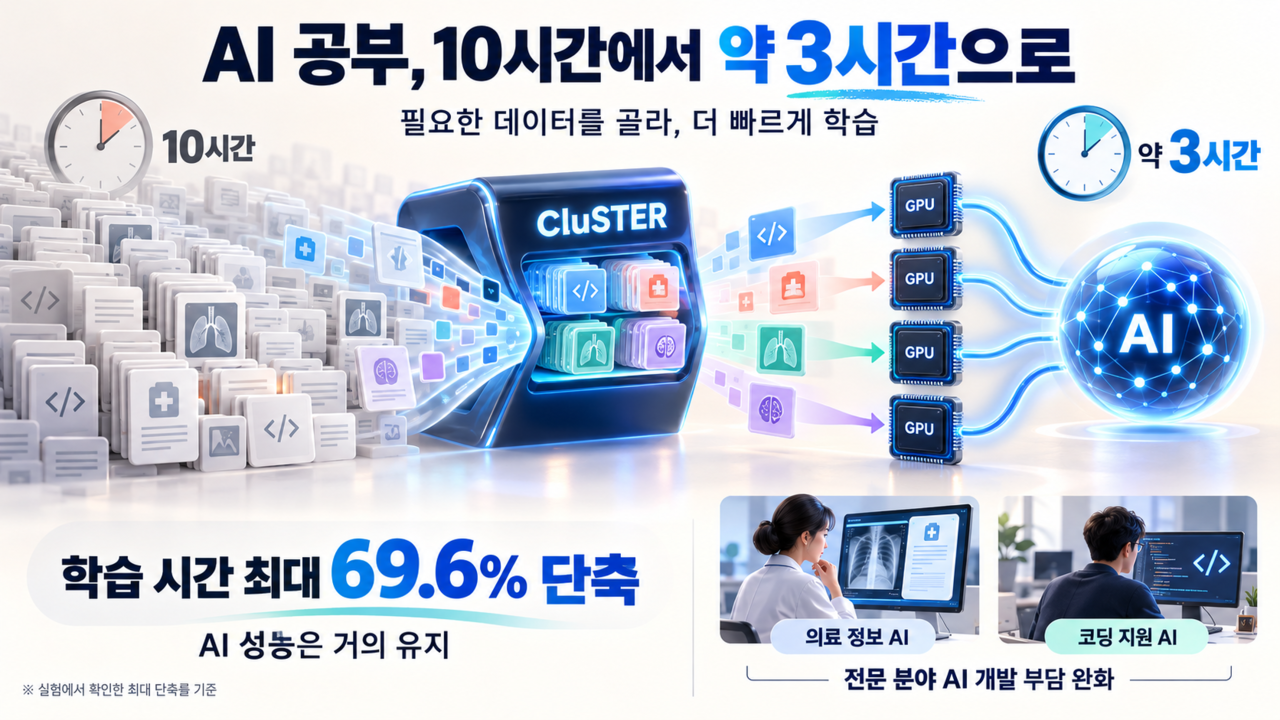
The technology is significant because it improves AI training efficiency without requiring additional GPUs. It is expected to ease the burden on companies and research institutions that develop customer service AI, medical support AI or coding assistance AI using their own proprietary data.
However, further validation across diverse corporate datasets and training environments will be needed before the technology can be applied in real-world industrial settings. Work also remains to refine the software so it can integrate smoothly with existing AI training systems.
"To improve AI training efficiency, it is important not only to use more GPUs but also to make smart choices about what data to train on," Lee said. "This research is meaningful in that it can reduce the training burden of large-scale AI models by making better use of existing GPU resources."
The findings were presented in October at EMNLP 2026, a leading international conference on natural language processing.
nbgkoo@heraldcorp.com