FuriosaAI, UC Berkeley joint research
Memory hierarchy simulation with HBF added
Greater KV cache reuse minimizes data-movement bottleneck
SK hynix pushes HBF standardization; Samsung develops NAND stacking technology
FuriosaAI has published simulation results on HBF (high-bandwidth flash) in collaboration with researchers at UC Berkeley, finding that adding large-capacity HBF to an LLM (large language model) inference environment reduced total task completion time by up to 86 percent compared with conventional systems. The research is drawing attention as the spread of AI agents intensifies demand for new memory hierarchy solutions.
FuriosaAI and UC Berkeley researchers recently released a paper titled "Characterizing HBF for LLM Inference Services," according to industry sources Wednesday.
The researchers ran simulations adding HBF to the memory hierarchy to address the lengthening inference contexts that come with the rise of AI agents. As AI inference activity grows, so does the need for greater storage capacity for KV cache (Key-Value Cache) — the intermediate computation results from previously processed context.
Until now, when HBM (high-bandwidth memory) capacity ran short, KV cache had to be offloaded to server DRAM or SSDs (solid-state drives). The simulation placed HBF close to the AI accelerator and assigned it responsibility for KV cache storage.
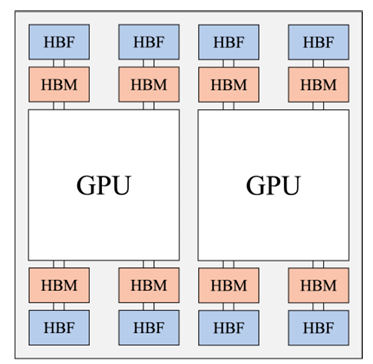
The researchers ran LLMs in a virtual environment with eight HBM units arranged around an AI accelerator and eight HBF units connected behind them. Using a simulator modeled on the computational performance of Nvidia's B200 GPU, they set per-stack capacity at 24 GB for HBM and 375 GB for HBF, giving each GPU a total HBM capacity of 192 GB and HBF capacity of 3 TB.
Both total task completion time and modeled energy consumption improved as a result. In a long-context dialogue environment using the GLM-5.2 model, total task completion time fell 86 percent compared with an HBM-only system, while energy consumption dropped 60 percent.
Frequently accessed data and newly generated KV cache were kept in HBM, while older cache expected to be reused was moved to HBF. Retaining KV cache in HBF longer and reusing it reduced the burden of fetching data from the server or recomputing context.
The memory chip industry has recently entered a race to capture the HBF market, which stacks NAND chips in a manner similar to HBM. SK hynix released an HBF standard specification jointly with SanDisk through the Open Compute Project (OCP) in August.
The specification defines capacity of up to 512 GB based on two stack configurations — eight-die and 16-die NAND stacks — and sets bandwidth across three grades (Grade 1 through 3), ranging from roughly 0.4 TB/s to 3.0 TB/s. The researchers also referenced SanDisk's HBF roadmap as background for their study and ran comparative simulations using the deployment architecture SanDisk proposed.
SK hynix positions HBF as a solution to inference bottlenecks by adding it to the existing memory and storage hierarchy — currently composed of HBM, server DRAM and SSDs. A key advantage, the company says, is improved cost efficiency relative to HBM.
Im Eui-cheol, SK hynix's executive vice president for solution AT, spoke on the topic at the Herald Corporate Forum 2026 late last month under the theme "In the AI era, memory is ultimately the key." He described HBF as offering "bandwidth comparable to HBM and capacity comparable to NAND flash, with the aim of increasing throughput at a lower price."
Samsung Electronics is also developing a next-generation technology that vertically stacks NAND chips, though under a different name. At FMS (Future of Memory and Storage) 2026 held in the United States in August, the company unveiled a mockup of "zNAND-O," optimized for on-device AI. The technology combines existing V-NAND with TSV (through-silicon via) interconnects to achieve 3D packaging of semiconductor chips in four- and eight-layer configurations.
jeongwan@heraldcorp.com